From Weights to Concepts: Data-Free Interpretability of CLIP via Singular Vector Decomposition
Vision-language models like CLIP map images and text into a shared embedding space. This simple...
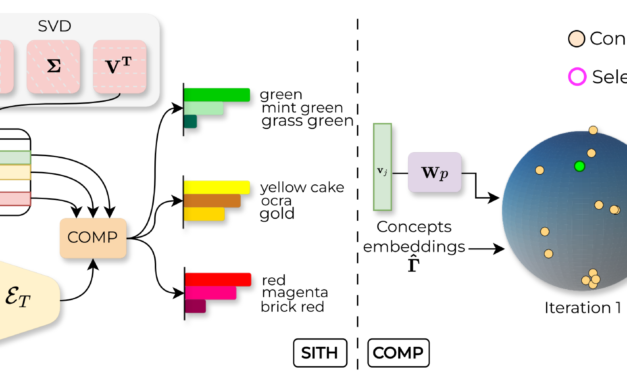
Vision-language models like CLIP map images and text into a shared embedding space. This simple...
Effective collaboration begins with knowing when to ask for help. For example, when trying to...
Building performant Vision-Language Models (VLMs) requires carefully curating large-scale training...
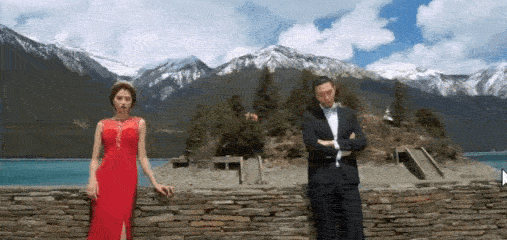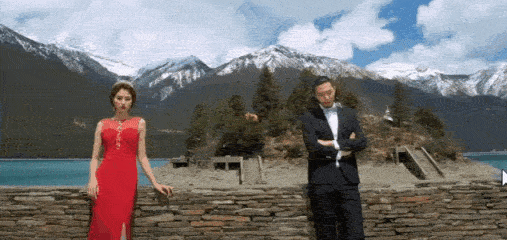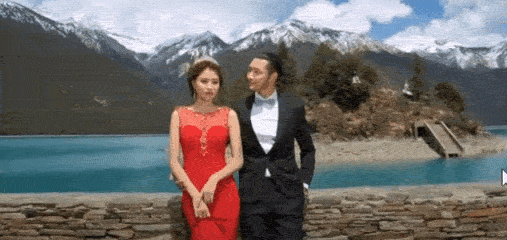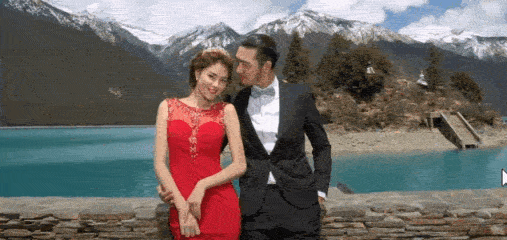
Given an input photo, memorability feedback aims to generate natural-language suggestions to guide users toward a more memorable shot. MemCoach provides memorability-aware feedback, effectively assisting users to capture memorable images.
